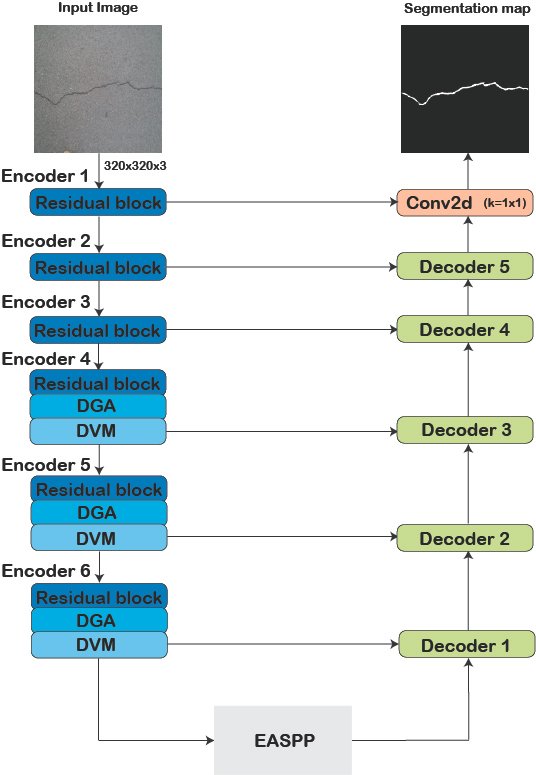
LiteFusionNet.
A lightweight road-crack segmentation architecture designed for efficient infrastructure monitoring under strict model-size and computation constraints.
Architecture Overview
LiteFusionNet is designed for road-crack segmentation where thin structures, cluttered road textures, and deployment constraints make dense prediction difficult. The architecture keeps a compact encoder–decoder structure while strengthening feature extraction through residual blocks, dilated gated attention, and dual vision mamba components. Its EASPP bridge captures crack-related context across multiple receptive fields, while the Dual-Level Decoder combines low-level spatial details with high-level contextual cues for sharper pixel-level localization. The result is an efficient segmentation model intended for infrastructure monitoring scenarios where accuracy, parameter count, and GFLOPs must be balanced rather than optimized in isolation.
Architecture Diagram